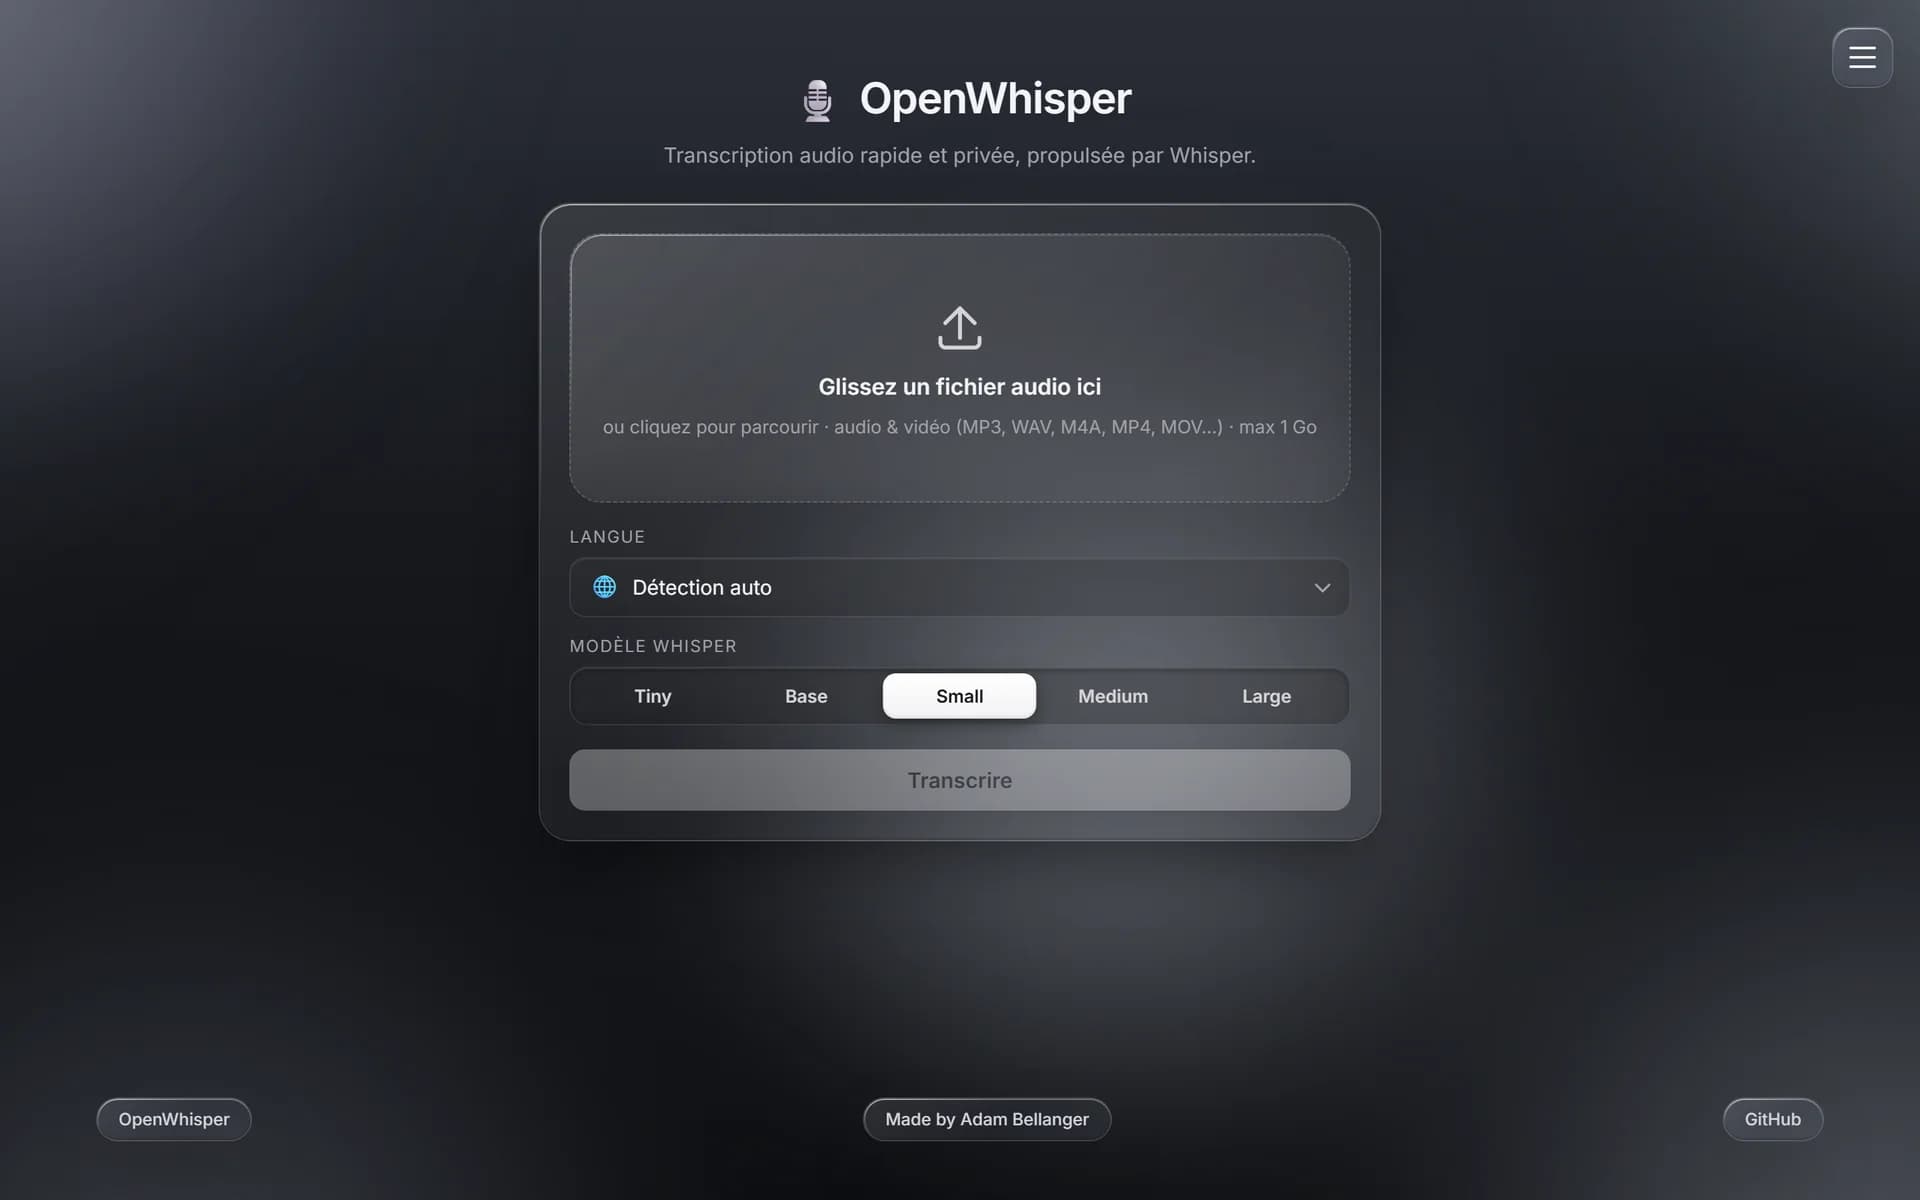
Audio transcription web app powered by Whisper, fully containerised and self-hosted.
Preview
Stack
- Languages
- TypeScript
- Front-end
- React
- Back-end
- Express
- Flask
- Whisper
- Infra
- Docker
- Nginx
Context
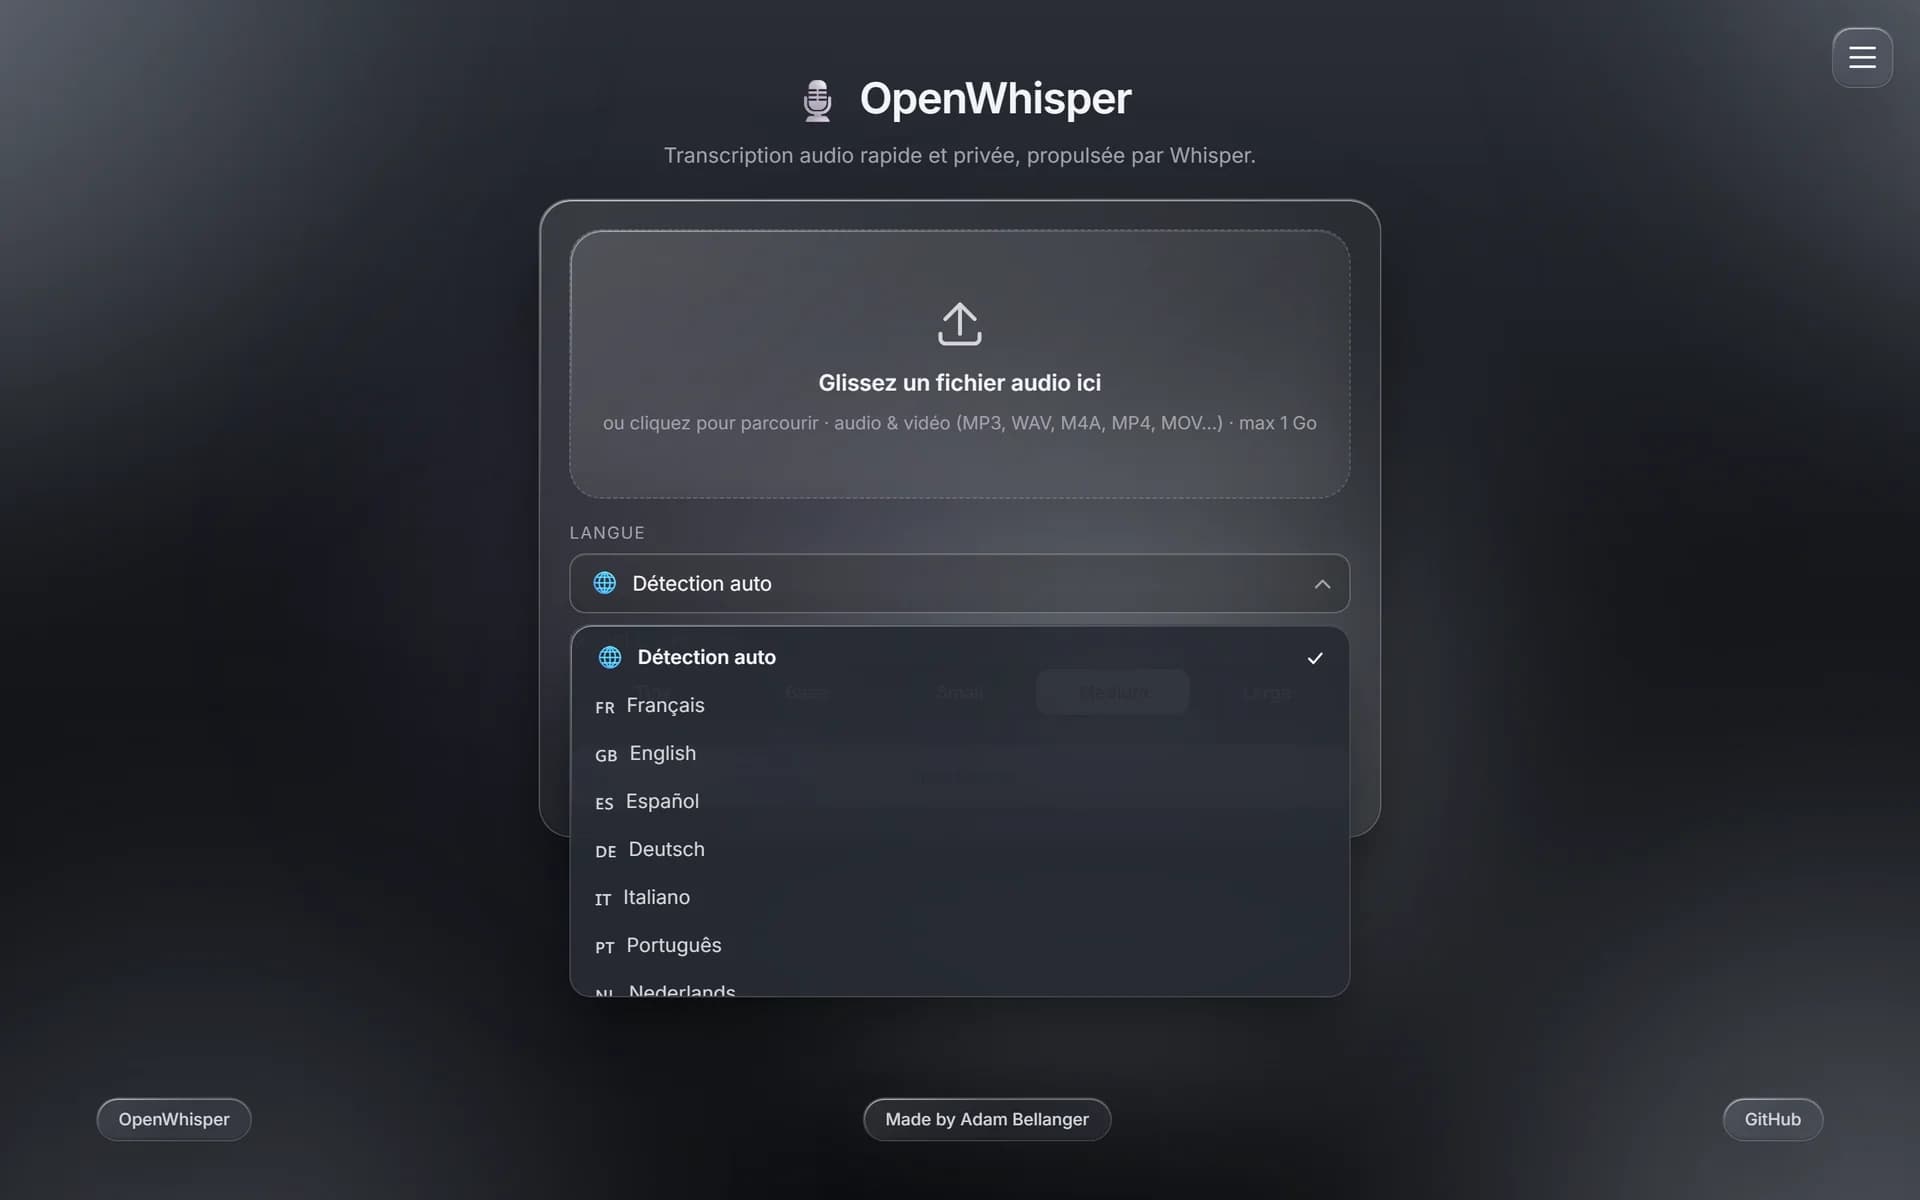
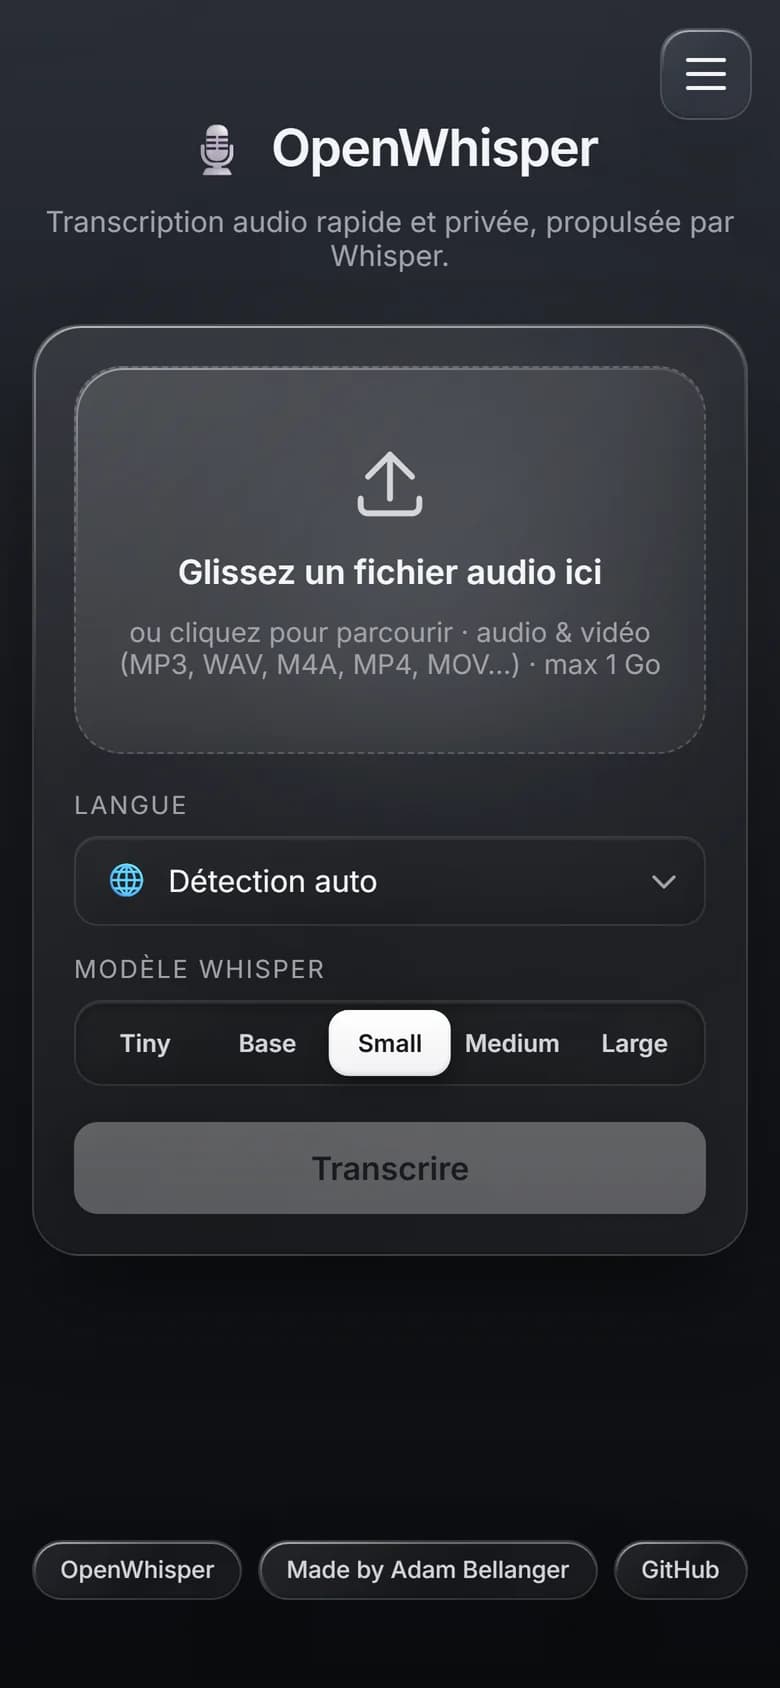
Transcribing audio files without sending them to a third party: a simple interface to drop a file, pick the language and model, and get the text back.
Role
End-to-end architecture and development, through to deployment on my server behind Nginx Proxy Manager.
Architecture
Browser
Audio file upload
Nginx Proxy Manager
HTTPS, single entry point
nginx frontend
Compiled React + /api proxy
Express gateway
:3001, multer upload
whisper-service
Flask :5000, Whisper + ffmpeg
Challenges
Splitting the app into three services (nginx frontend, Express gateway, Flask API + Whisper + ffmpeg) and exposing only the frontend: the backend and the transcription engine are never reachable from outside. The model is baked into the image at build time to remove cold starts.
Outcome
An app deployed with a single command (docker compose up), with model choice (small, medium, large), automatic language detection, progress tracking and a local history of recent transcriptions.
Highlights
- 3 isolated services, only one exposed
- Whisper model baked into the image, no cold start
- WAV, MP3, M4A, OGG and FLAC support